How AI works · measured on real GPUs
How AI actually works, with every number measured.
Open-weight models, probed layer by layer on a 96 GB Blackwell GPU, explained in long-form videos and full articles.
- 6episodes
- 96 GBRTX PRO 6000 Blackwell
- 2open Indic models
Series · 6 episodes
How AI Actually Works
A six-part series that opens up open-weight models on a 96 GB NVIDIA RTX PRO 6000 Blackwell GPU and measures what happens inside, from a single token to a video clip. Each part has a long-form YouTube video and a full article on Towards AI.
-
 EP 01
How ChatGPT Works: Why It Says Strawberry Has 2 R's
One question traced through Qwen3-4B: tokens, embeddings, attention, the logit lens, sampling, training and a live hallucination.
- #101830strawberry token
- 2,560dims per embedding
- 36layers
11 min full read →
-
 EP 02
Why AI Says “Wait”: How Thinking Models Work
What the Thinking toggle really does, why models say “Wait”, when more thinking hurts, and how GRPO teaches reasoning.
- 4 tokensthe whole toggle
- 99.99%real scratchpad
- 35.7%filler dots
11 min full read →
-
 EP 03
How LLMs Read a Whole Book: Long Context & KV-Cache
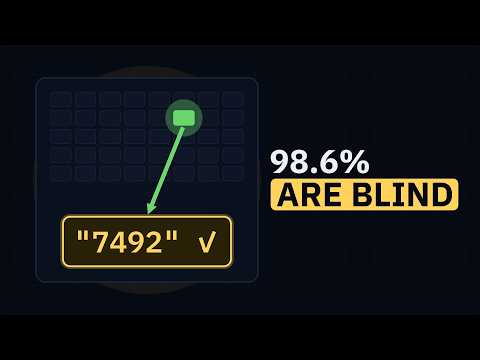
A passcode hidden in a 32,768-token book, and the attention heads, memory tricks and position clocks that find it.
- 32,768tokens read
- 2.04 sfull prefill
- 14.26 GBpeak VRAM added
8 min full read →
-
 EP 04
Why AI Clocks Say 10:10: How Image Diffusion Works
Diffusion, latent space and flow matching on FLUX.2 and SDXL, and why a 7:25 clock comes out as 10:10.
- 3,145,728numbers per image
- 65,536×cheaper attention
- 98.54%path straightness
18 min full read →
-
 EP 05
How Vision-Language Models See: ViT, CLIP, SigLIP
Why an “iPod” sticker fools CLIP, and how Qwen2.5-VL turns pixels into tokens a language model can read.
- 64.51%CLIP says iPod
- 1,600 → 400patches → tokens
- [16, 24, 24]M-RoPE t / h / w
22 min full read →
-
 EP 06
How AI Generates Video: Wan2.1 and Sora Explained
Wan2.1 on a real GPU: 3D causal VAEs, spacetime tubes, 3D RoPE, simultaneous denoising and why a ball vanishes behind a pillar.
- 10.12 → 27.74 dBframe consistency
- 32,760tokens per clip
- 975,015×attention cut
39 min full read →
Open models · Hugging Face
Open models for Indian languages
Two Apache-2.0 models for Indian-language text, released on Hugging Face: Yama, a zero-shot classifier, and Chitragupta, a personal-data detector and redactor.
-
MODEL 01 · Apache-2.0
Yama: Try a Bigger Encoder Before a New Architecture
Building Yama, a 586M zero-shot classifier for 11 Indian languages and Hinglish, and why the encoder swap beat every clever idea.
- 586Mparameters
- +5.3from a bigger encoder
- 0.814 vs 0.770unseen tasks
-
MODEL 02 · Apache-2.0
Chitragupta: Open-Source PII Redaction for India
Chitragupta, an Apache-2.0 model that finds and masks Aadhaar, PAN, UPI and other personal data in 13 languages, paired with Yama.
- 18PII types
- 13languages
- 0.959exact-span F1
Who is behind this
Arun Prabhakaran
Latent AI Labs is Arun Prabhakaran's independent AI-explainer channel. Each episode loads an open-weight model onto a GPU, records what actually happens inside it, and turns the numbers into an animated video and a full written article with paper citations.